AI 每日快讯

AI 每日快讯

AI 产品、模型、开源工具和官方动态的时间流。保留历史记录,按分类、日期和标签继续筛选。

3779历史快讯
207开源工具
80当前结果
10 月 02 日 今日快讯
MarkTechPost 官方资讯

MarkTechPost:Cloudflare Releases Clef and Clef-flash: Open-Weight Decision Models That Return Typed Proba…

原文摘要:Cloudflare has released Clef (27B) and Clef-flash (9B), open-weight decision models that return typed probabilities instead of text. They are Jev-API compatible, accept images, and 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。
10 月 01 日 昨日快讯
The Decoder 官方资讯

The Decoder:Nearly half of test subjects mistook Tavus' AI video avatar for a real person on a one-minut…

原文摘要:Tavus has introduced Griffin, what the company calls the first "Human Interaction Model." The AI holds video calls in real time, processing facial expressions, tone of voi 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Security startup finds more than 13,000 internal company screenshots that AI agents uploaded…

原文摘要:AI agents quietly posted more than 13,000 internal screenshots from 343 organizations, including Fortune 500 companies, to public GitHub repos. Because the platform didn't 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

InfoQ AI ML Data Engineering:Container Apps Express Reaches GA on a Newly Generally Available Sandbox Layer

原文摘要:Microsoft has made Azure Container Apps Express generally available alongside Container Apps Sandboxes, the microVM compute layer it runs on. Express skips environment provisioning 来源:InfoQ AI ML Data Engineering。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 30 日 2026-09-30 快讯
MarkTechPost 官方资讯

MarkTechPost:NVIDIA Researchers Introduce Physis-Lang: Self-Evolving Physical Language That Lifts Cosmos …

原文摘要:Video world models can render convincing clips that still break physics. Butter spreads like paint. Balls pass through walls. A team from NVIDIA, MIT and the University of Oxford a 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 29 日 2026-09-29 快讯

NVIDIA Developer 动态:Lower the Cost of Building and Running Visual AI Agents with NVIDIA VSS Blueprint 3.3

原文摘要:Vision-language models have made it possible to build visual AI agents that understand video at production scale. The harder problem is turning that capability... 来源:NVIDIA 开发者 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。
AWS Machine Learning 动态:How Condé Nast built multimodal video discovery with Amazon Bedrock

原文摘要:Condé Nast's editorial teams spent an average of 250 minutes per task searching a library of more than 140,000 videos using only titles and descriptions. Working with the AWS Gener 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Manus 2.0 lets users edit videos, host multiplayer games, and run agents remotely from their…

原文摘要:Manus is turning its AI agent into a platform with version 2.0, letting users edit videos, host multiplayer games, and run personal agents with their own phone numbers. Th 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 28 日 2026-09-28 快讯

AWS Machine Learning 动态:Generate images and video with vLLM-Omni on SageMaker AI – Part 2

原文摘要:Deploy two generative media models from one AWS vLLM-Omni Deep Learning Container on Amazon SageMaker AI. Generate an image with FLUX.2-klein through real-time inference, then anim 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

NVIDIA Developer 动态:How NVIDIA DSX MaxLPS Maximizes AI Factory Throughput and Efficiency

原文摘要:Every unused watt is capacity left on the table. AI factories are typically provisioned for the unlikely moment when every GPU reaches peak power, creating a... 来源:NVIDIA 开发者 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 26 日 2026-09-26 快讯
MarkTechPost 官方资讯

MarkTechPost:Sarvam AI Releases Saaras V4: A Speech-to-Text Model for All 22 Indian Languages and Global …

原文摘要:Sarvam AI's Saaras V4 is a speech-to-text model covering all 22 Indian languages plus global English. It pairs an audio encoder with a 3B hybrid state-space decoder. It adds keyter 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 25 日 2026-09-25 快讯
MarkTechPost 官方资讯

MarkTechPost:Liquid AI Releases LFM2.5-VL-3B-DSpark: Speculative Decoding for Vision-Language Models With…

原文摘要:Liquid AI has released LFM2.5-VL-3B-DSpark, a 279.5M-parameter draft model that brings speculative decoding to its LFM2.5-VL-3B vision-language model. It delivers up to 3.13x faste 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AWS Machine Learning 动态:Accelerate multimodal RL training with SkyRL on Amazon SageMaker HyperPod

原文摘要:Learn how to run SkyRL, an open-source reinforcement learning framework, on Amazon SageMaker HyperPod to post-train a Qwen3-VL-8B vision-language model with GRPO. This walkthrough 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

MarkTechPost 官方资讯

MarkTechPost:Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops Rob…

原文摘要:Black Forest Labs (BFL), the lab behind the FLUX image models, has released FLUX 3 Action. It is a 7B open-weights World Action Model (WAM) for robot control. The model reads camer 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 24 日 2026-09-24 快讯

AWS Machine Learning 动态:Speaker-labeled transcription with WhisperX on SageMaker AI

原文摘要:The AWS WhisperX Deep Learning Container packages Whisper, wav2vec2 forced alignment, and speaker diarization into a GPU-ready image. Learn how to deploy it to Amazon SageMaker AI 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

InfoQ AI ML Data Engineering:Apple Reference Image Signs Photos at the Sensor, Moving Provenance Trust Away from C2PA

原文摘要:Apple has published the design of Reference Image, an iPhone 18 Pro camera mode that signs pixel data at the sensor and develops it in Private Cloud Compute under an Apple signatur 来源:InfoQ AI ML Data Engineering。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 23 日 2026-09-23 快讯

AWS Machine Learning 动态:Agentic conversational video intelligence built on AWS

原文摘要:Learn how to build a conversational video intelligence solution on AWS using an agentic architecture. A single Strands Agents SDK agent orchestrates Amazon Bedrock, Amazon Rekognit 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Alibaba launches Qwen Audio 3.1 with new models and slashes AI audio prices by up to 95 perc…

原文摘要:Alibaba's AI team Qwen has released Qwen-Audio-3.1, a lineup of five models for speech recognition (ASR), text-to-speech (TTS), and real-time interaction. The ASR model im 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

InfoQ AI ML Data Engineering:Google Adds Cycle-Level Kernel Profiling to XProf

原文摘要:Google has added a Kernel Profiling suite to XProf. This is its open-source profiler for TPU workloads. Now, 开发者 can see cycle-level details in custom Pallas kernels. Before 来源:InfoQ AI ML Data Engineering。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 22 日 2026-09-22 快讯

AWS Machine Learning 动态:How Tata Elxsi detects industrial safety risks in seconds on AWS

原文摘要:Learn how Tata Elxsi built IRIS, a real-time industrial safety platform on AWS. IRIS filters camera video at the edge, streams metadata through Amazon Kinesis, runs computer vision 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 21 日 2026-09-21 快讯
MarkTechPost 官方资讯

MarkTechPost:Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editin…

原文摘要:Alibaba's Qwen team has released Qwen-Image-2.1, a 7B diffusion transformer that handles text-to-image generation, multi-reference editing, and native RGBA transparency in one chec 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:ByteDance launches Dramagic, a full-pipeline AI platform for producing short dramas from scr…

原文摘要:Bytedance launched Dramagic, an AI platform that handles the entire short drama production pipeline, from script to video preview. Demand for these videos is surging in Ch 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

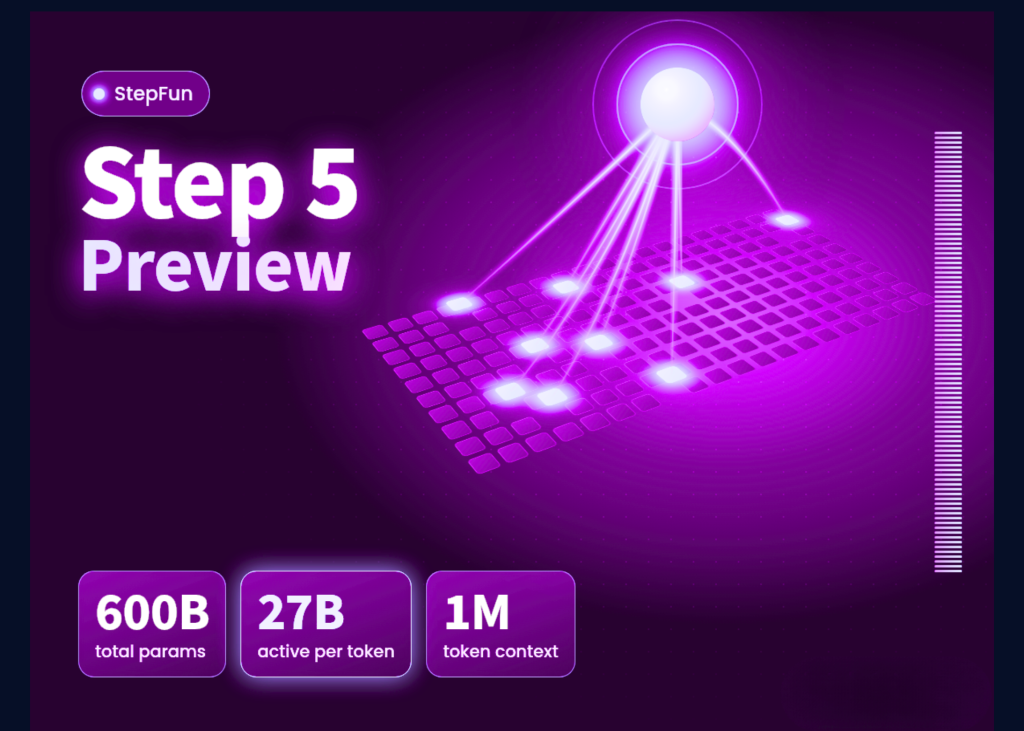
StepFun 发布 Step 5 Preview:600B 总参数 MoE,支持 1M 上下文

StepFun 发布了 Step 5 Preview,这是一个稀疏混合专家模型,总参数 600B、每 token 激活 27B,支持 100 万 token 上下文,并可接受文本、图像和视频输入。官方将其定位为面向软件工程、专业知识工作和金融等长周期 Agent 任务。API 已上线,输入每百万 token 收费 1 美元,输出每百万 token 收费 2.7 美元,开放权重也在计划中。值得关注的是,1M 上下文加多模态输入直接指向长程 Agent 场景,而按 token 计价的 API 让成本可估算。受影响的是做代码 Agent、深度研究和金融分析的开发者与团队。下一步可先用 API 跑一个长文档或代码库任务,验证上下文利用率和实际成本,再等开放权重发布后做本地评测。

09 月 20 日 2026-09-20 快讯
The Decoder 官方资讯

The Decoder:Alibaba's open-weight Qwen-Image-2.1 claims to beat closed models in image generation with j…

原文摘要:Alibaba's Qwen team has released Qwen-Image-2.1, an open-weight model that generates and edits images on powerful consumer GPUs, with support for transparency and up to te 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Runway wants to turn AI video generation into a live stream you control in real time

原文摘要:Runway wants to stream AI video as users prompt it, rather than make them wait for finished clips. The approach builds on GWM-1, its world model that generates video frame 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 19 日 2026-09-19 快讯
The Decoder 官方资讯

The Decoder:Qwen3.8-Omni-Flash undercuts Google's Gemini Flash pricing while matching its multimodal ben…

原文摘要:Qwen3.8-Omni-Flash is Qwen's first multimodal model designed for AI agents. It processes audio and video together and independently uses tools to edit vlogs, translate cli 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

MarkTechPost 官方资讯

MarkTechPost:SpaceXAI Releases Grok Voice Transcribe 2.0: A Speech-to-Text API Claiming 2x Accuracy Over …

原文摘要:SpaceXAI has released Grok Voice Transcribe 2.0, its newest speech-to-text model for batch and streaming audio. The company says it is twice as accurate as version 1.0 at the same 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 18 日 2026-09-18 快讯

AWS Machine Learning 动态:Introducing Kimi K3 on Amazon Bedrock

原文摘要:Kimi K3 from Moonshot AI is now available on Amazon Bedrock, giving you a powerful new open-weight option for coding and knowledge work. It offers native vision, a 1-million-token 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AWS Machine Learning 动态:The new AgentCore runtime: Elastic, optimized, and consistently fast starts

原文摘要:Today we are announcing the new AgentCore runtime, a capability of Amazon Bedrock AgentCore built for the speed, flexibility, and cost efficiency that production agents demand. It 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

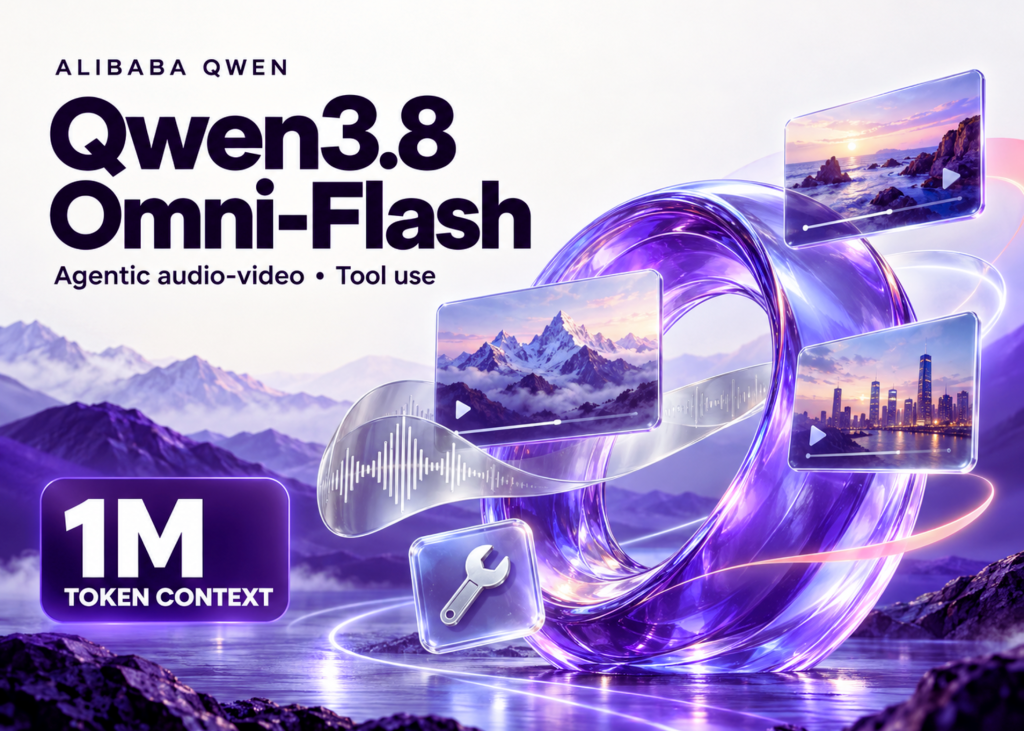
Qwen3.8-Omni-Flash 发布:百万上下文、音视频理解与工具调用

阿里 Qwen 发布 Qwen3.8-Omni-Flash,这是一个支持 100 万上下文的 omni-modal 模型,围绕 Agentic 音视频理解与工具使用设计,官方称在 OmniVideoBench 上减少约 45.7% 的 token 消耗。它值得关注的点有两个:一是把音频、视频理解和任务规划、工具调用放进同一个模型,二是长上下文叠加 token 效率优化,直接关系到 Agent 处理长视频或多模态任务的成本。影响的主要是做视频理解、会议分析、多模态 Agent 的开发者,以及需要处理长音视频素材的内容团队。验证方式:通过 Qwen 官方渠道申请或调用该模型,用一段带语音的长视频测试摘要与工具调用,记录实际 token 用量和延迟,再与现有方案做同任务对比。

09 月 17 日 2026-09-17 快讯

AWS Machine Learning 动态:Enhancing industrial safety AI with synthetic data on Amazon SageMaker AI

原文摘要:Learn how to build a synthetic data augmentation pipeline on Amazon SageMaker AI and Amazon Rekognition that generates photo-realistic, auto-labeled training images for industrial 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

MarkTechPost 官方资讯

MarkTechPost:Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up …

原文摘要:Nunchux AI has released VC-Attention, a training-free low-bit attention kernel built for video Diffusion Transformers (DiTs). It targets 2 problems at once: value quantization erro 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 15 日 2026-09-15 快讯
MarkTechPost 官方资讯

MarkTechPost:Google Releases Gemini 3.8 Live and 3.8 Live Extended Thinking for Production Grade Voice Ag…

原文摘要:Google has released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, its most advanced live dialogue models to date. The models execute tools and API calls in the background 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Google launches Gemini 3.8 Live to take on OpenAI's GPT-Live-1 at a fraction of the cost

原文摘要:Google Deepmind released Gemini 3.8 Live and 3.8 Live Extended Thinking, two new audio models for 开发者 that top the Artificial Analysis speech-to-speech leaderboard. 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 14 日 2026-09-14 快讯

AWS Machine Learning 动态:Manage end-user OAuth consent for AI agents with Amazon Bedrock AgentCore

原文摘要:Amazon Bedrock AgentCore Identity now offers a Consent portal, a managed web experience and session binding endpoint for AgentCore Gateway. This post walks through provisioning a p 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AI 资讯 官方资讯

AI 资讯:From Video to Data: How AI Is Transforming Multimedia Content Processing

原文摘要:A video looks simple when you press play. There is a picture, some dialogue, perhaps music in the background, and a few minutes later it is over. However, with the right use of AI, 来源:AI 资讯。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 11 日 2026-09-11 快讯

InfoQ AI ML Data Engineering:How LinkedIn Trains AI Job Search 8x Faster with Multi-Teacher Distillation

原文摘要:LinkedIn has published details of the training infrastructure behind its AI-powered job search, describing a multi-teacher distillation pipeline that compresses knowledge from larg 来源:InfoQ AI ML Data Engineering。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 10 日 2026-09-10 快讯

AWS Machine Learning 动态:Reduce inference cold starts on Amazon SageMaker HyperPod with model caching

原文摘要:Amazon SageMaker HyperPod now supports model caching for inference, which pre-loads model weights and container images onto cluster nodes so pods read from local NVMe storage inste 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AWS Machine Learning 动态:Video and image search in Amazon Bedrock Knowledge Base using Marengo 3.0

原文摘要:TwelveLabs Marengo Embed 3.0 is now generally available as an embedding model in Amazon Bedrock Knowledge Bases, bringing fully managed natural language search to video, image, and 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

NVIDIA AI 动态 官方资讯

NVIDIA AI 动态:Skild AI Taps NVIDIA Physical AI to Teach Robots New Tasks From a Single Video

原文摘要:Manufacturing floors, warehouses and production lines rarely stay fixed — tasks change, layouts shift and new products arrive, and most robots can’t keep up without significant rep 来源:NVIDIA AI 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 09 日 2026-09-09 快讯

AWS Machine Learning 动态:Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM

原文摘要:Learn how to deploy Qwen3.8-2.4T-A95B, a 2.4-trillion-parameter open-weight model, on Amazon SageMaker HyperPod with vLLM. This walkthrough covers cluster provisioning, NVFP4 quant 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

NVIDIA Developer 动态:When to Use Encode-Prefill-Decode Disaggregation to Accelerate Multimodal Model Serving

原文摘要:Encode-prefill-decode (EPD) disaggregation is an inference optimization technique for multimodal models that separates the vision encoder stage from the prefill... 来源:NVIDIA 开发者 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AWS Machine Learning 动态:Simplify and support your TorchServe workloads using Ray Serve Deep Learning Containers

原文摘要:TorchServe is no longer maintained, leaving teams to own the entire GPU inference stack. The AWS Ray Serve Deep Learning Container is a supported, pre-tested container with the fra 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 08 日 2026-09-08 快讯
AI 资讯 官方资讯

AI 资讯:YouTube Appears in 53% of Google AI Overviews for Vitamin and Supplement Searches

原文摘要:YouTube was the most frequently cited website in Google AI Overviews across a panel of vitamin and supplement searches, according to new research. The video platform appeared in 18 来源:AI 资讯。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 07 日 2026-09-07 快讯
The Decoder 官方资讯

The Decoder:Qwen-Drive 1.0 tells you why it brakes, just don't expect the explanation to match the maneu…

原文摘要:Alibaba's research arm has released Qwen-Drive 1.0, an AI model that handles environmental perception, traffic Q&A, and route planning in one system. The researchers show 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 06 日 2026-09-06 快讯
MarkTechPost 官方资讯

MarkTechPost:H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That D…

原文摘要:We look at NeoMME, a family of 260M and 800M bidirectional encoders from H Company. Unlike ColPali-style retrievers, it processes multilingual text tokens and raw 32×32 image patch 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:Meta's new real-time audio model is the foundation for AI assistants that never stop listeni…

原文摘要:Meta's Superintelligence Labs have released Muse Voice Transcribe, a real-time transcription model that processes speech in 80-millisecond chunks, tells speakers apart, an 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 05 日 2026-09-05 快讯
MarkTechPost 官方资讯

MarkTechPost:Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video Tokens by…

原文摘要:Gemini now navigates video instead of ingesting it at 1 FPS, loading only the segments a prompt needs. The post Google Launches Agentic Video Understanding for Gemini Flash Models, 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 04 日 2026-09-04 快讯

AWS Machine Learning 动态:Deploy a multimodal WhatsApp ordering assistant with Amazon Bedrock AgentCore

原文摘要:Learn how to deploy a multimodal WhatsApp ordering assistant that takes customer orders through text, voice notes, and real-time voice calls on a single business number, built on A 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

AWS Machine Learning 动态:Customizing your knowledge base on Amazon Bedrock for large and complex documents using Amaz…

原文摘要:Learn how to customize an Amazon Bedrock knowledge base for large, complex documents by combining the high-accuracy text extraction of Amazon Textract with the generative AI of Ama 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 02 日 2026-09-02 快讯

AWS Machine Learning 动态:Modernizing and scaling support operations with generative AI on AWS

原文摘要:Learn how to build a generative AI-based support operations platform on AWS that converts training videos into structured SOPs, applies Retrieval-Augmented Generation to guide tick 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:World Labs unveils Atlas, a single AI model that generates, reconstructs, and simulates 3D w…

原文摘要:World Labs, co-founded by AI researcher Fei-Fei Li, has announced Atlas, a world model that generates, reconstructs, and simulates 3D scenes from just a few images. The co 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

09 月 01 日 2026-09-01 快讯
MarkTechPost 官方资讯

MarkTechPost:Gradium AI Releases New Default TTS Model: 81.0% Hard-Case Pass Rate at 216 ms Time-to-First…

原文摘要:Speed and accuracy usually pull against each other in text-to-speech. Gradium AI's new default model reports both: an 81.0% human-rated pass rate on 500 hard sentences across five 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

08 月 30 日 2026-08-30 快讯

InfoQ AI ML Data Engineering:Cloudflare Extends AI Search to Make it Easier for Agents and 开发者 to Search Custom Da…

原文摘要:Cloudflare AI Search is a built-in search and retrieval service designed to give AI agents and applications a ready-to-use search engine over custom data. It supports agent integra 来源:InfoQ AI ML Data Engineering。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

08 月 29 日 2026-08-29 快讯
MarkTechPost 官方资讯

MarkTechPost:Google AI Releases Gemini Omni 1.1 Flash: 40-Second Scene Extension, First/Last Frame Contro…

原文摘要:We look at Gemini Omni 1.1 Flash, Google's production update to its native multimodal video generation and editing model. We break down what changed: scene extension now reads up t 来源:MarkTechPost。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:AI-generated videos are already displacing actors and livestreamers across China's entertain…

原文摘要:In China, 95 percent of the 128,000 short dramas released in Q1 2026 were AI-generated. Some actors are being forced to hand over their voice and likeness to AI tools befo 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

The Decoder 官方资讯

The Decoder:LAION drops massive open video dataset with 10 million hours of footage for AI research

原文摘要:LAION's Big Video Dataset (BVD) is one of the largest open video datasets for AI research, with 80 million videos, 10 million hours of runtime, and 55 million auto-describ 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

08 月 27 日 2026-08-27 快讯

AWS Machine Learning 动态:Build agentic creative 工作流 with Amazon Quick and fal

原文摘要:Creative teams produce more assets than ever, but fragmented tools and manual context transfer slow production. This post shows how to build a reusable agent harness with Amazon Qu 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

08 月 26 日 2026-08-26 快讯

Z.ai 发布 GLM-5.3-Flash:320B 参数原生多模态 MoE,上下文窗口达百万 Token

一句话结论:GLM-5.3-Flash 是 GLM-5 系列首个原生多模态模型,以 320B 总参数、18B 激活参数的 MoE 架构和 1M Token 上下文窗口亮相。原始信息显示,该模型权重采用 MIT 许可在 Hugging Face 开放,API 定价为输入 $0.15/M、输出 $0.50/M,在 Terminal-Bench 2.1 上得分 84.3,DeepSWE v1.1 上得分 63.4。技术上,它使用混合 KDA 线性注意力和 NoPE 稀疏 MLA 注意力,相比前代将注意力计算量减少约 3 倍,KV 缓存减少 4.4 倍。值得关注的原因是,百万级上下文和原生多模态能力使其在长文档处理、复杂代码生成和多模态推理场景具有竞争力,且 MIT 许可有利于商业应用。它影响的是大模型应用开发者、企业 AI 平台选型者以及研究多模态 MoE 架构的团队。下一步建议:在 Hugging Face 下载权重进行本地推理测试,或通过 API 试用,重点验证长上下文下的信息保持能力和多模态输入的实际效果。

AWS Machine Learning 动态:Bring your own model with Amazon SageMaker AI: Script mode in SDK v3

原文摘要:The SageMaker Python SDK v3 redesigns script mode with unified ModelTrainer and ModelBuilder classes. This post walks through two end-to-end examples, a scikit-learn Random Forest 来源:AWS Machine Learning 动态。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。

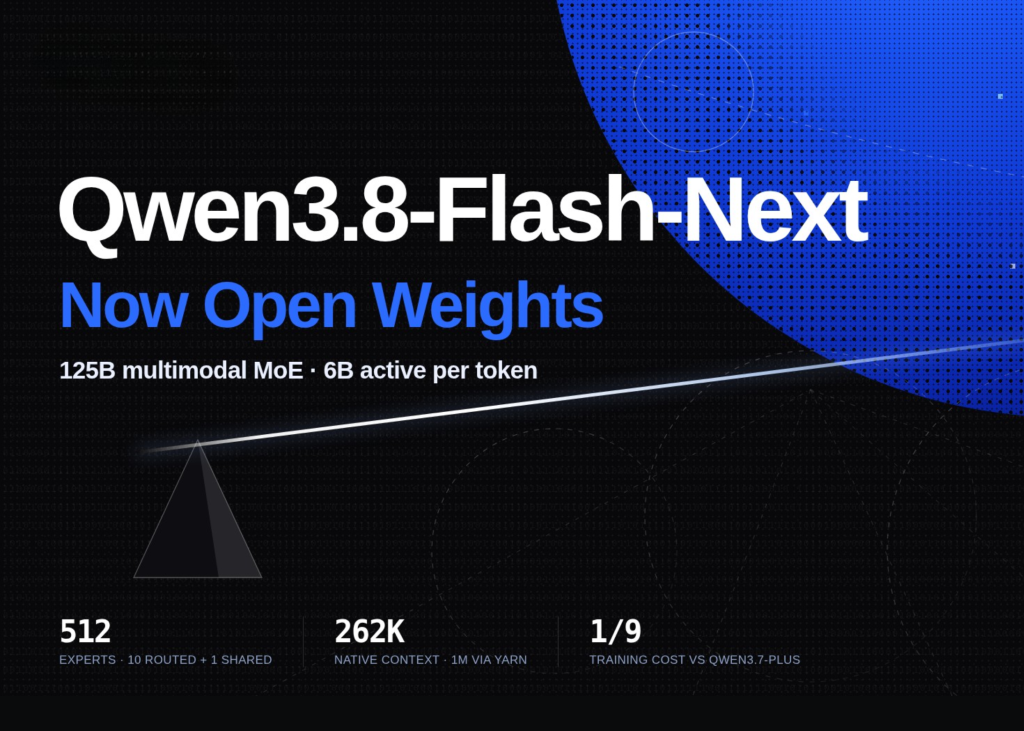
Qwen3.8-Flash-Next 发布:125B 多模态 MoE 模型预览 Qwen4 架构

一句话结论:阿里 Qwen 团队发布 Qwen3.8-Flash-Next,一个 125B 参数的多模态 MoE 模型,仅 6B 激活参数,并预览了 Qwen4 架构。原始信息详细拆解了参数分布:125B 主干、51B N-gram 嵌入表、4B 多 token 预测模块,每 token 仅激活 6B 参数。架构上引入了 Gated DeltaNet 与 Qwen Sparse Attention 的混合、Gated Res 等四项关键变化。为什么值得关注:这是 Qwen4 架构的首次公开预览,MoE 设计大幅降低推理成本,同时多模态能力可能带来更广泛的应用场景。影响谁:关注高效模型架构的研究人员、需要低成本多模态能力的开发者,以及使用 Qwen 系列模型的企业。下一步验证:可以等待模型权重开放后,在本地或云端测试其推理速度和多模态任务表现,并与现有 Qwen 模型对比。

The Decoder 官方资讯

The Decoder:Pro-Kremlin deepfakes put surrender rhetoric in the mouths of Ukrainian lawmakers

原文摘要:Pro-Kremlin Telegram channels are spreading AI-generated deepfake videos of two Ukrainian lawmakers who appear to call for peace talks. The clips racked up 130,000 views i 来源:The Decoder。建议继续查看原文,重点核对它影响的工具入口、成本、风险和真实使用场景。